Bangla & English ASR Studio — Whisper transcription, evaluation and fine-tuning
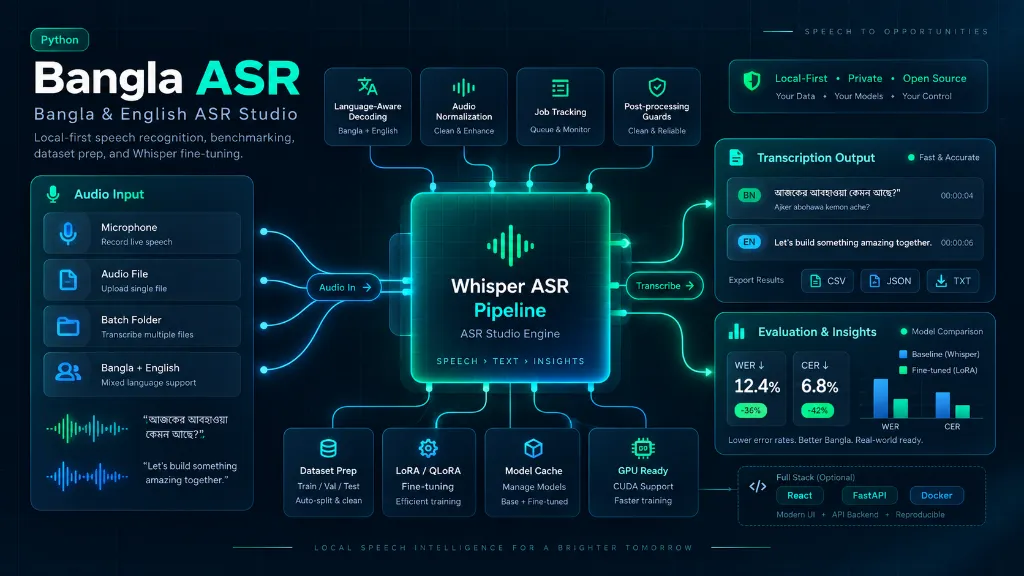
A local-first speech-to-text studio and Whisper fine-tuning pipeline for Bangla and English: transcription UI, batch jobs, WER/CER benchmarking and guarded LoRA training.
The problem
Off-the-shelf Whisper models work well in general, but production Bangla and mixed Bangla/English (Banglish) audio raises practical problems: Bangla can be misdetected as another Indic language, and mixed-language speech needs controlled decoding and repeatable evaluation.
Fine-tuning without a fixed baseline creates a grey area — there is no evidence that the new model is actually better than the one it replaces.
Architecture and approach
- A React operator UI for microphone and file transcription, batch jobs, benchmarks, diagnostics and training controls.
- A FastAPI backend that handles model loading, audio normalisation, job tracking, exports, evaluation and training subprocesses.
- CLI scripts for the same operations, so GPU servers and automation do not depend on the UI.
- Docker Compose stacks for CPU, development with hot reload, and an NVIDIA GPU override.
Key features
- Benchmarking against ground-truth metadata with word error rate (WER) and character error rate (CER), plus per-sample predictions.
- Bangla/English decoding profiles and post-processing guards.
- Training and evaluation directly from Parquet datasets (e.g. SUBAK.KO from Hugging Face) without extracting every clip to WAV, including a streaming mode.
- LoRA/QLoRA fine-tuning of Whisper, training small adapter layers instead of all model weights.
- Resumable segmented dataset downloads and a persistent model cache that survives container rebuilds.
Engineering decisions
- Guarded training workflow: back up the current model, evaluate it on a fixed held-out test set, train, evaluate the new model on the same set, then write a side-by-side comparison with confusion analysis.
- The pipeline never auto-replaces the production model. The comparison reports a verdict (new better, old better, or mixed metrics) and the final decision stays manual.
- The test split is kept fixed and untouched so old-vs-new comparisons stay fair.
Technology stack
- Speech & ML
- Whisper
- faster-whisper
- Hugging Face Transformers
- LoRA / QLoRA
- PyTorch
- Backend
- Python
- FastAPI
- FFmpeg
- Frontend
- React
- Vite
- Infrastructure
- Docker Compose
- NVIDIA CUDA (GPU override)